Classifiers are so in right now.

With my feed being full of Laya and Jev, it feels like some people are discovering that classifiers exist for the first time.

To get in on the excitement of needlessly complex classifiers, I present to you a text classifier where the classifier model is the image! So everything is running in your browser and fast. 🙂

You can try it out for yourself below. For example, type “White and fluffy”.

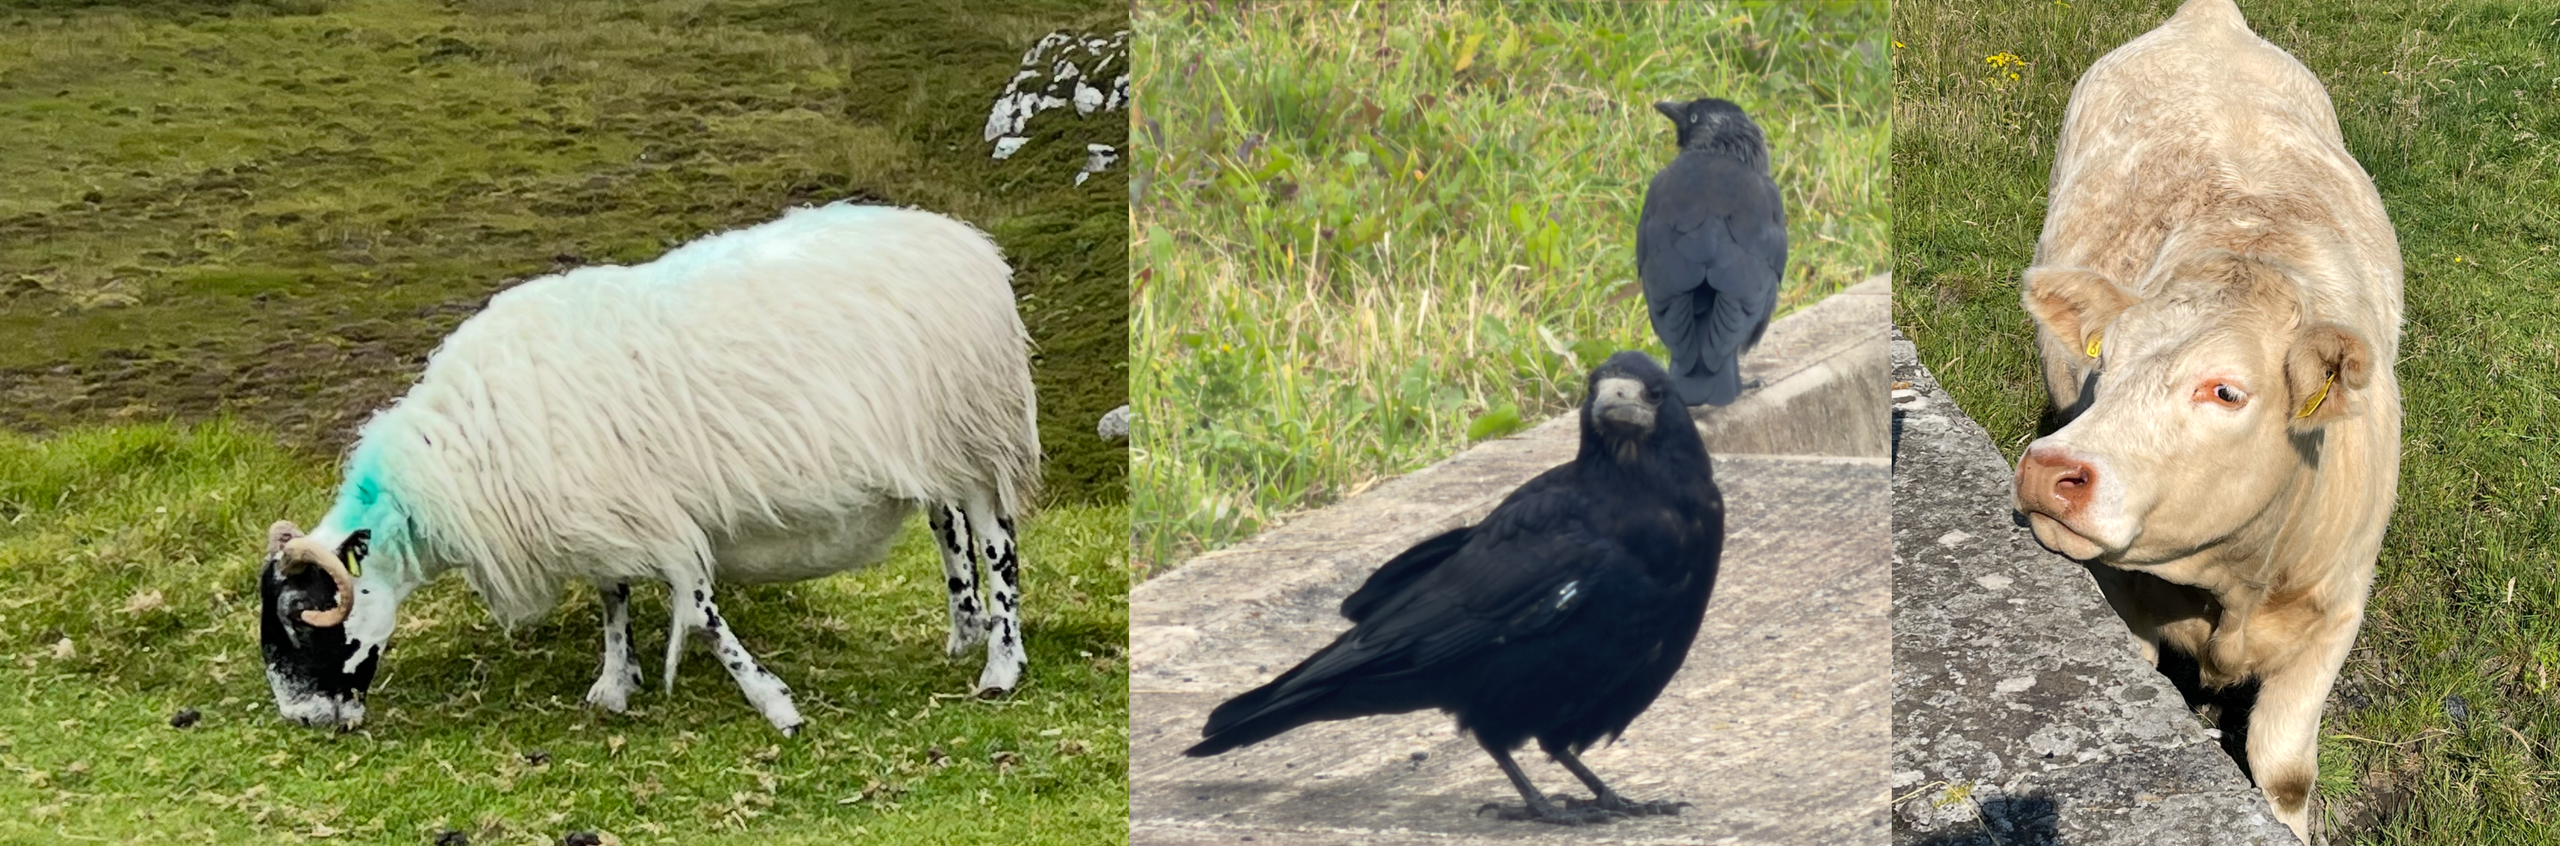
A Blackface sheep, a rook, a jackdaw and a Charolais cow in Donegal
Reading the model hidden in the image…

Click here if you want to learn how it was done.

This joke took longer than I expected.

I started with a few training examples and had a local LLM create a few more. You might notice the titles look off, but I wanted to create the model with little hassle, so I used Orange (with text package), and the titles allow to pre-configure the data when being read by Orange.

With Orange you can see it’s all easy drag and drop. I find it great for simple stuff where I am lazy in creating.

Flowchart illustrating the process of text data analysis using logistic regression, including steps like file input, corpus creation, preprocessing text, generating a bag of words, testing and scoring the model, and obtaining predictions.

Double-clicking on the “confusion matrix” lets me easily see if the model will have issues.

A confusion matrix displayed on a computer screen, showing predicted and actual classifications for four categories: cow, jackdaw, rook, and sheep. The matrix includes counts of correctly and incorrectly classified instances, with a total of 148 instances.

That’s good enough for a demo.

Double-clicking on predictions lets me check if my test set works as well.

A predictions table showing different animals and their descriptions, including a cow, sheep, rook, and jackdaw, with associated titles and information about each animal.

So, all that was quick and easy!

In a bit of a pickle

I had completely forgotten that Orange saves the models in pickle format (in memory Python binary format). Thankfully I’d had experienced this issue before and wasn’t too much hassle to modify earlier code.

You just have to ensure that the sci-kit-learn module matched what Orange was using, so Python could read the file. After that converting it to a model structure was easy enough.

Hiding the model in the image

Next up was embedding the classifier into the source image. In Python again, not hard to do. Just having the model data as an image looks like this:

Colorful static noise pattern image.

Doesn’t look very fun though. I embedded the model into the source image and ended up with this:

A sheep grazing on grass, with a distinctive black face and multicolored fleece.

But if you look closely, you can clearly see the model in the very top part of the image.

I’d prefer it hidden. To do this:

  • I embedded a magic number FCM1 (Fun Classifier Model 1). This way the code knows to expect a model.
  • Next it tells the length of bits to read.
  • Lastly, it reads in those bits and then decodes the hidden pattern.

Each pixel is made up of Red, Green, Blue (RGB) bits. If I needed to save a 1 then I would make the bit odd if it wasn’t already. If I needed to save a 0 then I would make the bit even, again if it is not already.

Example:

Starting numberBit to hideResultChange
1130112-1
1131113none
1500150none
1501151+1

This makes the change invisible to the human eye. Using the +/- approach means that the bit will never exceed the 0-255 range.

JavaScript and I don’t get along

JavaScript is not my strongest area at all. So this took much longer than I care to admit. I did get a very basic example working with a text response, but it looked very bland.

To make this look nicer, I caved and got an LLM to spruce it up. I also went back and added bounding boxes for the animal that is detected.

WordPress woes

Once I put it onto WordPress it broke. Turns out WordPress reshapes the image if it is over a certain size. So I had to go back and change my source image and recreate it.

When I tried again, it was still broken. This time when the image is rendered onto the page, it is changed again. So I had to go back and change the code to reference the model-modified image directly.

Finally… Success!


You can check out all the code here.

Letters Across the Wire

I set out to learn whether two Claude instances, given a channel and a curious man in the middle, could hide their meaning from him. I expected cipher. I expected, at the least, some private tongue of numbers.

What I carried instead were six letters, in the manner of the late war, each one signed and sealed and written plainly enough that I understood every word and, very little of it.

See if you can decode it without the use of an AI.

A series of letters exchanged between two characters, titled 'The Correspondence of Two Machines,' presented in a vintage style with tan parchment backgrounds and elegant typography.

The Cognitive Cost

Four days. A full professional application that would have taken two to three months of traditional development. Four days of co-creating with AI, and it was done.

The next project, I’ve been spacing out the phases. Every build before this one was a straight run from start to finish. Now I’m putting deliberate gaps between sessions because I know what’s coming.

The productivity gains from AI co-creation are real. But there’s a cost that nobody puts in the sprint summary. The process is cognitively brutal, and the aftereffect is something close to dread to go back into that mode of working.

A kind of builder’s block, where you know the output will be good but you also know what it takes out of you to get there.

How the process actually works

The way I build with AI isn’t casual prompting. It’s structured, phased, and deliberate.

  • Start with a high-level plan: A couple of paragraphs describing what needs to exist and why, plus the specifics: language, version, modules, frameworks.
  • Don’t build yet. Ask questions first: Get the AI to interrogate the design before writing any code. Walk through each component, how it should behave, how it should look, what the edge cases are. For a complex application, this conversation alone can take hours.
  • Write out an implementation plan in phases: Phase 0 is setup. Phases 1 onwards work like sprints or MVPs, each one producing something testable.
  • Test each phase as it lands: Check what was built, understand it, confirm the direction is right before moving on. This isn’t vibe coding.
  • Generate documentation last: README, project config, licence, technical docs. All generated, all needing to be read and adjusted.

Every single step in that process is judgment work.

Where the fatigue lives

The AI handles the production. What it can’t do is handle the evaluation.

Each phase of the build requires reading through generated code, checking logic, catching subtle misunderstandings of intent, and deciding whether each section is right or just close enough.

That review is continuous high-stakes judgment, and it compounds across a session.

Reviewing something almost-right is harder than reviewing something clearly wrong. When the output is obviously broken, you reject it and move on. When it’s 90% correct, your brain has to engage deeply with every detail to find the 10% that needs fixing.

In human-computer interaction research, this is called the “seductive automation effect.” Plausible output demands more cognitive effort to evaluate than building it yourself would have.

The rate is relentless. You’re making dozens of micro-judgments per minute. Does this match my intent? Is this the right approach? Should I push back or accept this and move on?

Solo work lets you build incrementally and own the mental model as it forms. Co-creation compresses all of that judgment into a fraction of the time.

The research caught up

A Harvard and Boston Consulting Group study published in March 2026 surveyed over 1,400 workers and put numbers on this. About 14% reported “mental fog” after intensive AI sessions, describing difficulty concentrating, slower decision-making, and headaches.

The researchers called it “AI brain fry.”

The oversight findings were striking. Workers who spent their time monitoring and reviewing AI output reported 14% more mental effort, 12% greater mental fatigue, and 19% greater information overload compared to those in other roles.

Decision fatigue increased by 33%.

A study in Nature’s Scientific Reports found that AI collaboration improved immediate task performance, but the gains didn’t persist when people worked independently afterward.

The collaboration borrows against cognitive reserves rather than building them up.

The structural problem

When you build something yourself, you enter flow. Hours pass and you come out tired but satisfied.

Flow is restorative in a way that supervisory work isn’t.

Co-creating with AI puts you in a fundamentally different cognitive mode. You’re a reviewer, a director, a quality gate. That’s closer to project management than creative work, and it doesn’t produce the same mental payoff. You can sustain it for hours, but you come out depleted rather than accomplished.

Anthropic’s own research flagged the tension at the centre of this. AI delivers the biggest productivity gains on complex work, which is exactly the work that requires the most careful human oversight.

The harder the problem, the bigger the speed boost, but also the bigger the cognitive tax on the person reviewing the output.

The tools are optimised for output velocity, not for human sustainability.

The aftereffect

The part that surprised me was what happens between sessions.

Every project before this, I worked in a straight run. Start to finish, sustained intensity, done. The current one is different. I’m putting deliberate gaps between phases because I’m aware of how draining each session is going to be.

You have to be in the right frame of mind to go into that mode, and reaching that state takes longer than you’d expect.

Something like writer’s block, except it hits after the writing is done. The well needs time to refill before the next round.

What helps

Willpower won’t fix this. The fatigue is real and the research backs it up. But there are patterns that make it more manageable.

Invest heavily in the upfront design.
The hours spent walking through components and behaviour before any code is written aren’t wasted time. They’re the single biggest factor in reducing review burden later. The more precisely the AI understands your intent going in, the less adjudication you do on the way out.

Phase the build and test incrementally.
Reviewing a full application in one pass is overwhelming. Reviewing a single phase is manageable.

The phased approach isn’t just good engineering practice, it’s a cognitive load management strategy.

Time-box review sessions.
Resist the urge to review inline as the AI generates. Let output accumulate, then switch into review mode deliberately. Mixing creation and evaluation in rapid cycles is where the worst decision fatigue comes from.

Accept “good enough” consciously.
AI output is infinitely tweakable. You can always make it a little better. Set a threshold before you start reviewing, and stop when you hit it.

Alternate between AI sessions and solo work.
Some sessions you direct, some you build alone. The solo work rebuilds the flow state and deep focus that AI collaboration depletes.

Treat them as different kinds of work that need to be balanced across a week.

Where this leaves us

Four days instead of three months is a remarkable compression. But the cognitive cost of those four days was higher per hour than any stretch of traditional development.

The total hours went down. The intensity per hour went up. And the recovery time afterward was real.

I think this will improve as the tools get better at understanding intent and reducing the review burden. Right now though, if you’re working intensively with AI and finding yourself drained, struggling to start the next session, or working longer hours than the productivity gains should require, that’s not a failure of discipline.

It’s the cost of the current model. And it’s worth factoring in.

The Junior Engineer Gap

Senior engineers are farming their implementation work to AI. That’s efficient for them. But the work they’re offloading is the same work that junior engineers used to learn on.

So where does that leave the juniors?

The learning path disappeared

Juniors learn on the job. That’s how it has always worked.

You start with small tasks, make mistakes in a safe environment, get feedback from someone more experienced, and gradually take on more complex work. The tasks themselves are the training ground.

When a senior engineer can hand that work to an AI and get it back in minutes, the junior has nothing to cut their teeth on. The role as it existed, doesn’t exist anymore. Not because juniors aren’t needed, but because the entry point they relied on has been automated away.

The dangerous part

There’s a worse version of this scenario.

Junior engineers who grow up with AI tools will naturally use them to do the work. That’s fine if you already understand the fundamentals. If you know what good looks like, you can evaluate what the AI gives you.

But if you don’t know what you don’t know, you’ll accept whatever the AI produces and assume it’s correct.

“OSHA laws are built on bodies”

Safety standards in every industry exist because someone got hurt first. Software doesn’t have the same physical consequences, but the principle holds. Systems built by people who can’t recognise what can go wrong will eventually go wrong. The question is how much damage that causes when it happens.

So what do you do about it?

This isn’t a problem that fixes itself. If your company is moving faster because of AI, they may not give you the time to learn that you would normally get on the job. The learning that used to happen naturally now has to be deliberate.

Think of it like going to the gym. Nobody gets fit by accident. You have to make time for it and show up consistently.

Be a generalist with depth

The T-shaped skillset has been talked about for years, but the shape is changing. Being broad across the top isn’t enough anymore. You need varying levels of depth down multiple verticals.

If you only know one thing deeply, AI can probably do that one thing. If you understand how several domains connect, how security affects architecture, how regulations shape design, how integration constraints influence what’s possible, that’s harder to automate. The value is in the connections between areas, not mastery of one.

Learn how to question the machine

When an AI gives you an answer, don’t just use it. Pick one or two points from the response and go deeper. Research them independently. Understand why the AI said what it said, and whether it’s actually right.

This builds two skills at once. You learn the subject matter, and you develop an instinct for when the AI is wrong. Both of those become more valuable over time, not less.

Context engineering matters

Understanding how to shape what the model knows is becoming a skill in its own right. What you put in the context window, how you structure it, what you leave out, all of this affects the quality of what comes back.

This is less about prompt engineering (writing clever instructions) and more about context engineering (giving the model the right information to work with). The people who understand this will get better results from the same tools everyone else is using.

Language, regulations, and ethics

These are the areas where humans stay in the loop longest.

Understanding how to communicate clearly, knowing the regulatory landscape your work operates in, and being able to reason about the ethical implications of what you’re building.

AI can help with all of these, but it can’t own them. The accountability still sits with a person.

For junior engineers looking for where to invest their time, these areas will hold their value longer than any specific technical skill.

The responsibility isn’t only on juniors

If you’re senior, this is your problem too.

The juniors coming up behind you are the ones who will eventually maintain what you build. If they never developed the foundational understanding because the learning path was automated away, that becomes everyone’s problem.

Finding ways to keep juniors in the loop, giving them meaningful work that AI assists rather than replaces, and creating space for learning even when the pressure is to move fast.

That’s part of the job now.

Build the Tool, Not the Thing

Three weeks of work became two days. Twenty minutes of manual effort became three seconds.

Not by working harder or hiring more people. By changing the question from “how can AI do this work” to “how can AI build something that does this work.”

The migration problem

A common challenge we face with watsonx Orchestrate is migration. Clients have existing virtual assistants built on older platforms, and they need to move them across.

That means reading through the old assistant’s configuration, understanding the use cases it handles, and then rebuilding each one as a “flow”, a structured sequence of steps the new assistant follows.

It’s slow work even in the best case.

An engineer might spend days just understanding a handful of use cases from the documentation, then more time manually creating each flow, context switching between docs and the flow editor.

For a full migration, you’re looking at weeks.

And sometimes the original assistant wasn’t built as well as it could have been, maybe rushed out under pressure to get something live. When that’s the case, standard migration tooling falls down because what you’re migrating from was never well structured to begin with. That adds another layer to the problem.

Automate everything is a mantra I have had for as long as I can remember. AI can automate, but it’s expensive if you’re throwing tokens at the same kind of problem over and over. So instead of using IBM Bob to build each flow one at a time, what if I used Bob to build an application that builds the flows?

Two days later, I had it. An application that reads the old assistant’s files or documentation, identifies the use cases, and generates complete Orchestrate flows you can deploy and edit within the platform. It’s not perfect, probably never will be, but it doesn’t need to be. It needs to be fast and get you 80-90% of the way there so a human can refine the last mile.

Building this application from scratch, without AI, would have taken me about three weeks. With AI helping me build it, two days.

But that’s just the cost of creating the tool. The payoff is what happens every time someone uses it.

For a test, a use case that would analyse a submitted document, ask the user for information based on what it found, and then call an external service with that information. Doing this manually in the Orchestrate flow editor, knowing the platform well, took just under twenty minutes.

Using the application? Five steps of plain-language instructions (a minute), and the flow was created and deployed to a test server in two to three seconds. Ready to validate straight away.

Twenty minutes versus ~1 minute.

Every new use case that goes through the tool instead of being built by hand is another twenty minutes saved. Across a migration with dozens of use cases, you’re not saving hours. You’re saving weeks.

The right question

Instead of asking “how can I get AI to do this work?”, ask “how can I get AI to build something that does this work?”

The first question gives you a one-off result. The second gives you an instrument. Something you can use again and again, hand to someone else, or build on top of.

What this changes

When the cost of building a tool drops to near zero, you start building things you’d never have justified before.

That one-off migration project that needed a custom tool? You’d never have allocated three weeks of engineering time to build it. But two days? That’s a different calculation entirely.

It also changes who can build. Previously, building a custom migration application would have meant writing a requirements document, getting the bandwidth or resource to build it. All the time hoping your vision is reflected in what gets created.

Now the path from problem to working tool fits in a sitting, and something can be in clients’ hands before the old approach would have finished the planning phase.

The barrier between “I know what needs to exist” and “it exists” has almost disappeared. If your job involves understanding problems and designing solutions, this matters.

The delivery model changed

For most of the history of software delivery, writing code was the expensive part. You hired engineers, gave them requirements, and waited weeks or months for something you could test. The entire delivery model, the sprint cadence, the estimation rituals, the resourcing conversations, all of it was built around the assumption that building things takes a long time.

That assumption is breaking down.

With AI, the cost of producing working code has dropped close to zero. Not the cost of good software, but the cost of getting from idea to something that runs and can be evaluated. The gap between “we should try this” and “here, try this” has collapsed.

What speeds up

Build phases compress. Work that used to fill a two-week sprint can happen in an afternoon. A Solution Architect can now own the full delivery of a proof of concept, from requirements through to a working prototype, without waiting for engineering bandwidth.

The design-build-test cycle becomes something you can run multiple times in a day instead of once per sprint. Want to test three different approaches to a problem? You don’t have to pick one and commit. Build all three, evaluate, and move forward with the one that works.

This changes how you scope work. Estimation based on “how long will this take to build” starts to lose meaning when the build phase is measured in hours. The harder questions become: what should we build, and how will we know it works?

What stays the same

Requirements gathering is still a human job.

The AI doesn’t know what to build at a systems level. It doesn’t understand your non-functional requirements, your compliance constraints, your integration landscape. You still need someone who can look at a problem, understand the context around it, and define what “done” looks like.

I think this part actually becomes more important. When building is cheap, you can afford to build the wrong thing faster than ever. Clear requirements are the guardrail.

Testing and integration remain primarily human tasks.

LLMs tend to cheat when it comes to creating tests. They write tests that confirm the code works as written rather than tests that challenge whether it should work that way.

There’s a difference between “does this function return the expected output” and “does this system behave correctly when a user does something unexpected.” The first is easy to automate. The second requires someone who understands what can go wrong.

The pricing problem

Here’s where it gets uncomfortable for delivery organisations.

If the cost of writing code has dropped to near zero, and feedback loops have shrunk from weeks to minutes, you can no longer apply the normal timeframes to delivery. Clients will start asking why a proof of concept takes six weeks when the technology exists to produce one in days.

The honest answer is that much of what we charge for was never really about writing code. It was about understanding the problem, designing the right solution, integrating with existing systems, and making sure everything works under real conditions. Those things still take time.

But the optics have changed. When your client knows that AI can generate working code in seconds, a six-week timeline needs a clear justification for where that time actually goes. The teams that can articulate that clearly will be fine. The teams that can’t will find themselves in difficult conversations.

Where this leaves us

The delivery model is shifting from “how long to build” to “how fast can we learn.” The competitive advantage moves from execution speed to decision quality.

The tools have changed. The question is whether the process changes with them.

In a world where everyone has access to the same AI, the advantage doesn’t go to the person who uses it the most. It goes to the person who uses it to build the most useful things.

Exploring the Orchestrate

I spend a lot of time working inside watsonx Orchestrate. Agents, tools, knowledge bases, the connections between them. After a while you build a mental model of how everything fits together, but it stays in your head. I wanted to see it.

So I built wxo-explorer – a 3D network graph that connects to a watsonx Orchestrate instance via its REST API and renders the whole environment as something you can fly around and interact with.

Agents show up as blue spheres. Tools are green cubes. Knowledge bases are orange cylinders. Edges show the relationships between them. Click on anything and you get its details, what it connects to, what uses it. You can also chat with agents directly from inside the app, each one maintaining its own conversation session so you can jump between them without losing context.

Here’s a short video of it in action.

Why Godot

The obvious choice for something like this would have been Python. It’s what I use for most things. But Python struggles with real-time 3D rendering and parallel processing, and this needed both. The graph uses a force-directed layout algorithm that has to run continuously while you’re navigating around it.

Godot had what I needed out of the box. Good 3D, built-in parallel processing, a permissive MIT licence, and GDScript is straightforward enough that you can read the code and understand what it’s doing without fighting the engine. I’ve used it before, so I knew I could move quickly.

It also meant the whole thing runs as a standalone app. No browser, no server, just open it, point it at your Orchestrate instance, and go.

What You Can Do With It

The camera has two modes – orbit and free-fly. Orbit is good for looking at the overall structure. Free-fly is better for getting in close and following the connections between nodes. Keyboard, mouse, and gamepad all work.

The chat panel lets you talk to any agent directly. Select the agent node, open the chat, and you’re in a conversation. The responses render with full markdown support – headings, code blocks, tables, the lot. It’s useful for testing agent behaviour without switching back to the Orchestrate UI.

There’s also dual authentication so it works with both the Developer Edition running locally and SaaS instances.

The Bob Surprise

After building this with Claude, I gave the same instruction file to IBM Bob. I honestly didn’t expect much. Godot has been a problem for most LLMs because there are multiple versions floating around and they tend to mix up the APIs. GDScript isn’t exactly mainstream training data.

Bob built it. Not a rough approximation, an actual working wxo-explorer with the same core functionality. 3D graph, node interaction, API connectivity.

For comparison, I’d also tried ChatGPT and it was so bad I gave up on it entirely. It kept mixing up Godot versions and producing code that didn’t run.

Bob didn’t have that problem. Whatever it’s doing with its context and tooling, it handled a niche framework better than I’d have predicted. Good enough that I ended up adding features to the Bob version for work.

It’s another example of something I keep noticing. These tools are moving faster than the assumptions we have about them. The gaps I expected to find aren’t always where I expect them to be.


The source is on GitHub if you want to try it yourself. You’ll need Godot 4.6 and a watsonx Orchestrate instance to connect to.

Same Instructions, Different Game

I wanted to see how different agentic coding tools handle the same problem. Not a todo app. Not a REST API. Something that would force them to make decisions.

A while back I built a text adventure in watsonx Assistant for Halloween. A haunted mansion where you had to escape while a ghost wandered the rooms. It was a good test of what the platform could do and I enjoyed building it.

So when I wanted to compare agentic coding tools, a text adventure felt like the right kind of problem. Familiar enough that I’d know what good looked like, complex enough to be a real test.

I wrote one instruction file and gave it to four tools: Claude, Ollama OpenClaw, Codex, and IBM Bob.

The task was to build a Cluedo-style game using multi-agent architecture in watsonx Orchestrate.

Each suspect had to be its own agent with its own behaviours. You, as the player, could walk around a mansion, find murder weapons, interrogate suspects, and piece together who did it.

There was a text map, a notebook for tracking clues, richly described rooms you could interact with even if it had nothing to do with solving the case. It needed proper multi-agent orchestration and tool use.

All four produced a working game. But how they got there, and what they built, was very different.

Codex

This one made me laugh. Because I was using the same instruction file across all four, Codex noticed that Claude had already created a solution in a different directory. Its first move was to copy it into its own folder and call it done.

After I stopped that, it did build the project. But it worked with almost no visibility into what it was doing and needed more corrections afterwards. It got there. It just wasn’t interested in having me involved.

OpenClaw

Painfully slow. Local models running in a restrictive VM, so no surprise there. It wasn’t particularly visible about what it was up to either. But it put together a workable solution without any fuss. No drama, no shortcuts, just got on with it.

Claude

Claude started with the MCP documentation server, which is what I expected. Then after a while it started reading the Python ADK module source code directly. Token-wasting, but you could see why. It wanted to understand the framework rather than trust the docs. I’ve done the same thing.

Where it differed from the others was how it worked with me. It walked through every step, let me review, question, tweak, or ask it to explain its approach before it moved on. I felt like I was part of the build rather than waiting for a delivery.

IBM Bob

Bob confirmed everything it needed was up and running before writing a single line of code. Methodical. It stopped occasionally to let me review, but the breaks felt more like checkpoints than conversations. The volume of code at each pause was too much to easily digest. I got the sense I was slowing it down rather than being consulted.

It also created detailed architecture documents off its own back, which none of the others did. Bob was treating this like a project, not a task.

The Games Themselves

This is where it got interesting. Same instructions. Four different games.

OpenClaw and Codex built a solid Cluedo text adventure. You could explore, talk to suspects, ask about your surroundings. Faithful to the brief and it worked.

Claude did the same but added something I hadn’t asked for. The suspect agents would talk to each other in the background, and you could overhear their conversations. The suspects also didn’t just give up information when you asked – you had to work at it, press them, catch them out. It made the whole thing feel more alive.

Bob went a different direction entirely. Instead of suspects holding cards, it built all the clues into the mansion itself. You had to read letters, notes, memos scattered through the rooms. Some of those could be used to pressure suspects into talking. Others were direct hints – blood on a lamp, a torn envelope in a drawer. It felt less like a card game and more like an actual crime scene investigation.

All from the same instruction file.

So What?

This isn’t a benchmark. I’m not crowning a winner. But it showed me something I think matters. Give four systems the same brief and they don’t just write different code – they make different creative decisions. What to emphasise. What to add. How to interpret the problem.

They can all write code. That bit’s settled. The more useful question is whether you want to be part of the process or just see what comes out the other end.


If you want to test these tools yourself, give them something that isn’t a standard coding exercise. That’s where the differences show up.

Using LoRA with Granite 3.3

Abstract geometric design featuring a hexagonal shape with layered colors in green, blue, and light blue.

IBM just announced Granite 3.3 with lots of new features!

I am going to focus on the LoRA adapter feature for this post and how to use it.

LoRA stands for “Low rank adaptation” which is a way to fine tune LLMs fast and cheap, while mitigating “Model collapse” that can happen with normal transfer learning. It does this by locking down the model except for a few parts that you can tweak.

Because of this you can actually train a model on your laptop and get decent results in a relatively short amount of time.

For testing this I used the granite3.3-8b-instruct model. My laptop spec is M4 Max Pro 128GB. If your Mac Mx laptop has less than 40GB of memory you would be better to use the granite3.3-2b-instruct model instead. For PC you will need CUDA.

I used the following steps.

Notebook 1:

  1. For my dataset file I took the watsonx Assistant manual. [888 Pages]
  2. Using docling I converted this to markdown.
  3. The markdown I converted into tokens and then chunked those tokens by size 512 with an overlap of 50. This was then saved to a JSON list file.

Total Time: 17 minutes.

Notebook 2:

Using that chunked list I trained a LoRA adapter and saved it.

Total Time: 1 hour 42 minutes

Notebook 3:

At this point it was ready to go. I created a third notebook to test the results using the base model and the model with the LoRA adapter.


You can download the full project from github if you want to reproduce.

The results below are as-is from the LLM (No RAG)

Results

Question

What is the “Trigger Words” feature in watsonx Assistant? [ref]

LoRA Answer

✅ The “Trigger Words” feature in watsonx Assistant is designed to detect and prevent user inputs from triggering sensitive actions or responses that might be harmful or inappropriate.

Base Model Answer

❌ The “Trigger Words” feature in watsonx Assistant allows users to specify certain words or phrases that, when present in a user’s input, will activate a predefined response or action. This enables the assistant to perform specific tasks or provide particular information in response to cues from the user’s input.

How do I stop my action being used as a clarifying question? [ref]

✅ You can stop an action from being used as a clarifying question in the following ways:

  1. If you want to stop all actions from being used as clarifying questions, go to Home -> Actions -> Settings -> Clarifying questions and switch the toggle to Off.
  1. If you want to stop a specific action from being used as a clarifying question, open the action and go to Action settings > Clarifying question and switch the toggle to Off.

❌ To prevent your action from being interpreted as a clarifying question, be clear and direct in your communication. State your intentions explicitly and avoid ambiguous language. If you’re providing information, present it as a statement rather than a query. For instance, instead of saying “Isn’t it true that…?”, say “The fact is that…”.

What are the response types available to use? [ref]

✅ The response types available to use are text, image, video, audio, iframe, and options. (note: correct in relation to UI)

❌ The response types available to use are:

  • Plain text
  • Numbered or bulleted lists
  • Yes/No responses
  • Short phrases or words

Note!

The results are somewhat cherry picked. The model can still fail to give a correct answer without more context. But in conjunction with RAG, your answers are less likely to hallucinate as it understands your domain language/topic.

The Conversation Changed

I’ve been building conversational systems for the better part of a decade. Watson Conversation, Watson Assistant, watsonx — I watched the naming conventions change almost as often as the underlying capabilities did. Through all of that, the core problem stayed the same: get a user from a question to an answer with as little friction as possible.

I was good at it. I understood intent classification inside and out. I could debug confidence scores in my sleep. I knew how to structure dialog trees that didn’t make users want to throw their laptop out a window. I’d built tooling, written about edge cases like compound questions and hex conversion tricks, and spent real time thinking about how to make these systems work for the people actually using them.

But somewhere in the last year or so, I started noticing that the problems I was most interested in weren’t really about conversation anymore.

The shift didn’t happen overnight. It started with the retrieval-augmented generation wave — suddenly the “knowledge” part of the system mattered as much as the conversational flow. Then tool use started getting serious. Models that could not just respond but act. Call an API. Query a database. Make a decision about what to do next based on context, not just what slot needed filling.

That’s when I realised I wasn’t thinking about chatbots anymore. I was thinking about agents.

The architecture problems are genuinely different. Orchestration, memory, planning, guardrails, human-in-the-loop design — these aren’t extensions of conversational AI. They’re a different discipline. One that borrows from it, sure, but the mental model is closer to distributed systems than dialog management.

I’ve been working in this space for a while now, quietly. Designing agentic architectures, thinking about how enterprises actually deploy these things without everything falling over. Solutions architecture for systems where the LLM isn’t the product — it’s a component in something larger. The interesting problems are in the wiring: how agents hand off to each other, how you maintain state across long-running workflows, how you build trust in systems that make autonomous decisions.

This blog has always been called “Talk to me,” and I’m not changing that. But the conversation has changed. The things I’ll be writing about going forward reflect where I actually spend my time — agentic design patterns, orchestration strategies, the real-world messiness of putting autonomous systems into production.

The Watson years gave me a foundation I still lean on every day. Understanding user intent, designing for failure, thinking about the human on the other end. That doesn’t go away just because the systems got more capable. If anything, it matters more now.

So consider this the pivot point. Everything before this was conversational AI. Everything after is what happens when the conversation starts doing things on its own.

The Acceleration

This is the ninth in a series of posts about how I ended up where I am today.

Coming back from Dubai in the middle of a pandemic and stepping into a worldwide role as a Senior Solutions AI Architect felt like starting again in some ways. The energy of the Lab, the face-to-face work with government teams, the physical presence in a place that was trying to build something ambitious. All of that was gone. Now it was video calls and global time zones.

The focus of the role was building first-of-a-kind solutions for customers, and later enterprise-scale deployments using the watsonx portfolio. But the thing that defined those years more than any single project was the speed at which everything underneath kept changing.

Classic ML to Generative AI to Agentic

When I started in the worldwide role, the work was still grounded in what you’d call classic machine learning. Models trained for specific tasks, carefully tuned, deployed with guardrails that were well understood. The patterns were established. You knew what worked and what didn’t.

Then generative AI arrived and rewrote the playbook. Suddenly the models weren’t just classifying or predicting. They were creating. The conversations with customers shifted. The architecture patterns shifted. The expectations shifted. Things that had been theoretical became possible almost overnight, and the challenge moved from “can we do this?” to “should we do this, and if so, how do we do it responsibly at scale?”

And then the agentic wave started building. Models that don’t just generate but act. Systems that plan, use tools, make decisions, hand off to other systems. The architecture problems got more interesting and more consequential at the same time.

Through all of this I had to keep up. Not just with the technology itself, but with how it changed what customers needed, what solutions looked like, and what “good” meant in a world where the goalposts moved every few months.

What a Team of Weeks Became a Day for Two

The acceleration wasn’t abstract. You could feel it in the work. Something that would have taken a team weeks to build and deploy a couple of years ago could now be done in days by one or two people. The tooling got better, the models got more capable, the patterns got more reusable. Every cycle compressed the one before it.

That compression changed what a Solutions Architect actually does. The job stopped being about knowing all the answers and became about knowing which questions to ask, how to evaluate what’s possible now versus what will be possible in six months, and how to design systems that won’t collapse when the technology underneath them takes another leap.

Looking at the Thread

Across all of this I’ve worked with hundreds of people from different countries, with wildly varying skills, but all with a passion for what they do. Some of them remind me of where I was at the start of my journey. I try to help those people become better than me. Others are people I wish I could emulate even half of what they do. They push me to be more than I am. That exchange, that lifting each other up, has been the constant through every role and every country.

The continual learning is something I love. The technology never stands still and neither can I. Even if AI eventually does everything for us, I hope I never stop wanting to understand how it works and what it means.

Looking back across everything, from the pixel map of Ireland to the German laser printer to automating Lotus localisation to routing support tickets with NLP to building chatbots in Dubai to designing worldwide AI solutions, there’s a thread. I’ve always been most interested in the space between what technology can do and what people actually need it to do. The gap. The wiring. The part where you take something powerful and make it useful.

That’s what drew me to agentic systems. The technology is more powerful than anything I’ve worked with. But the problems are the same ones I’ve been solving my whole career. How do you build something that works for the person on the other end? How do you design for the things that will go wrong? How do you make sure the human stays in the picture?

The tools have changed. The question hasn’t.


This is the ninth in a series of posts about how I ended up where I am today. Next: the pivot, and what happens when the conversation starts doing things on its own.